Speech-to-text, speaker identification, and audio classification from real transcription work we've delivered.
Anonymized samples from our audio work: transcription, timestamps, and labeling.
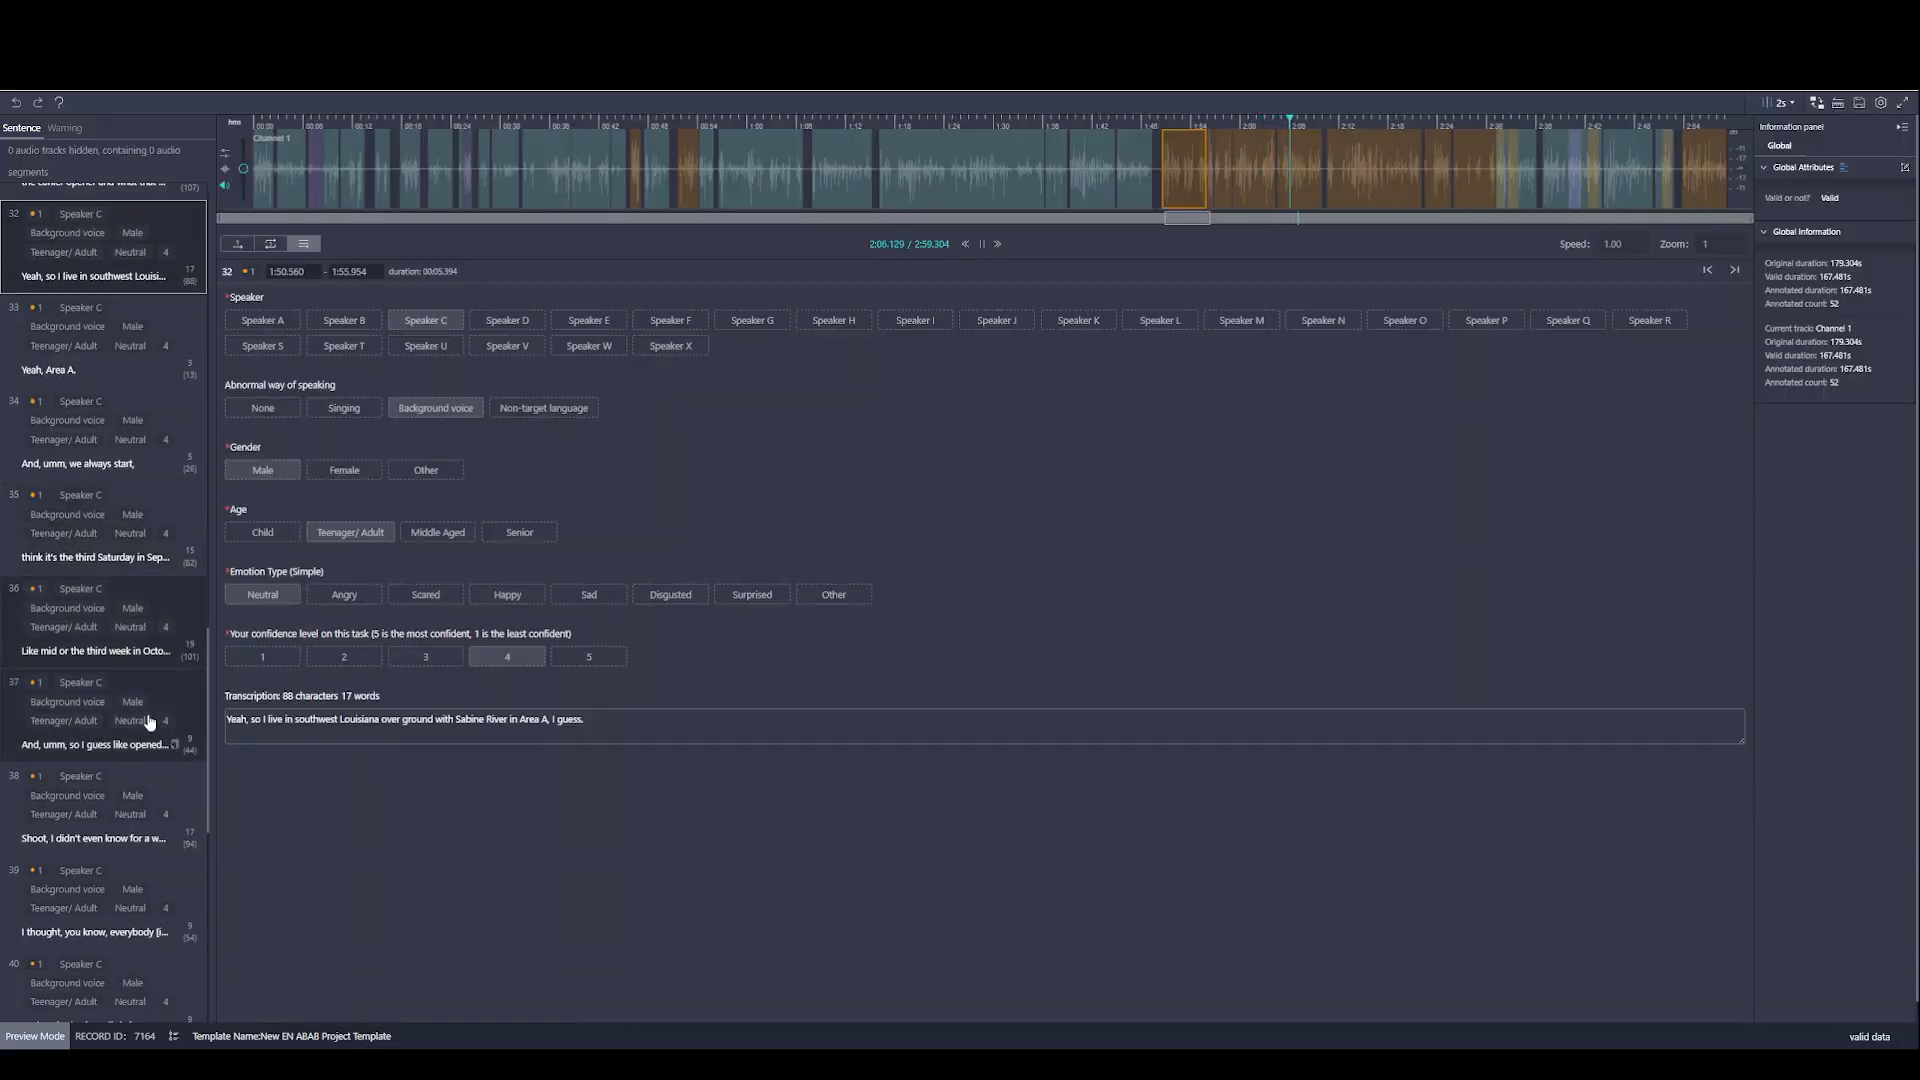
Verbatim transcription with timestamps
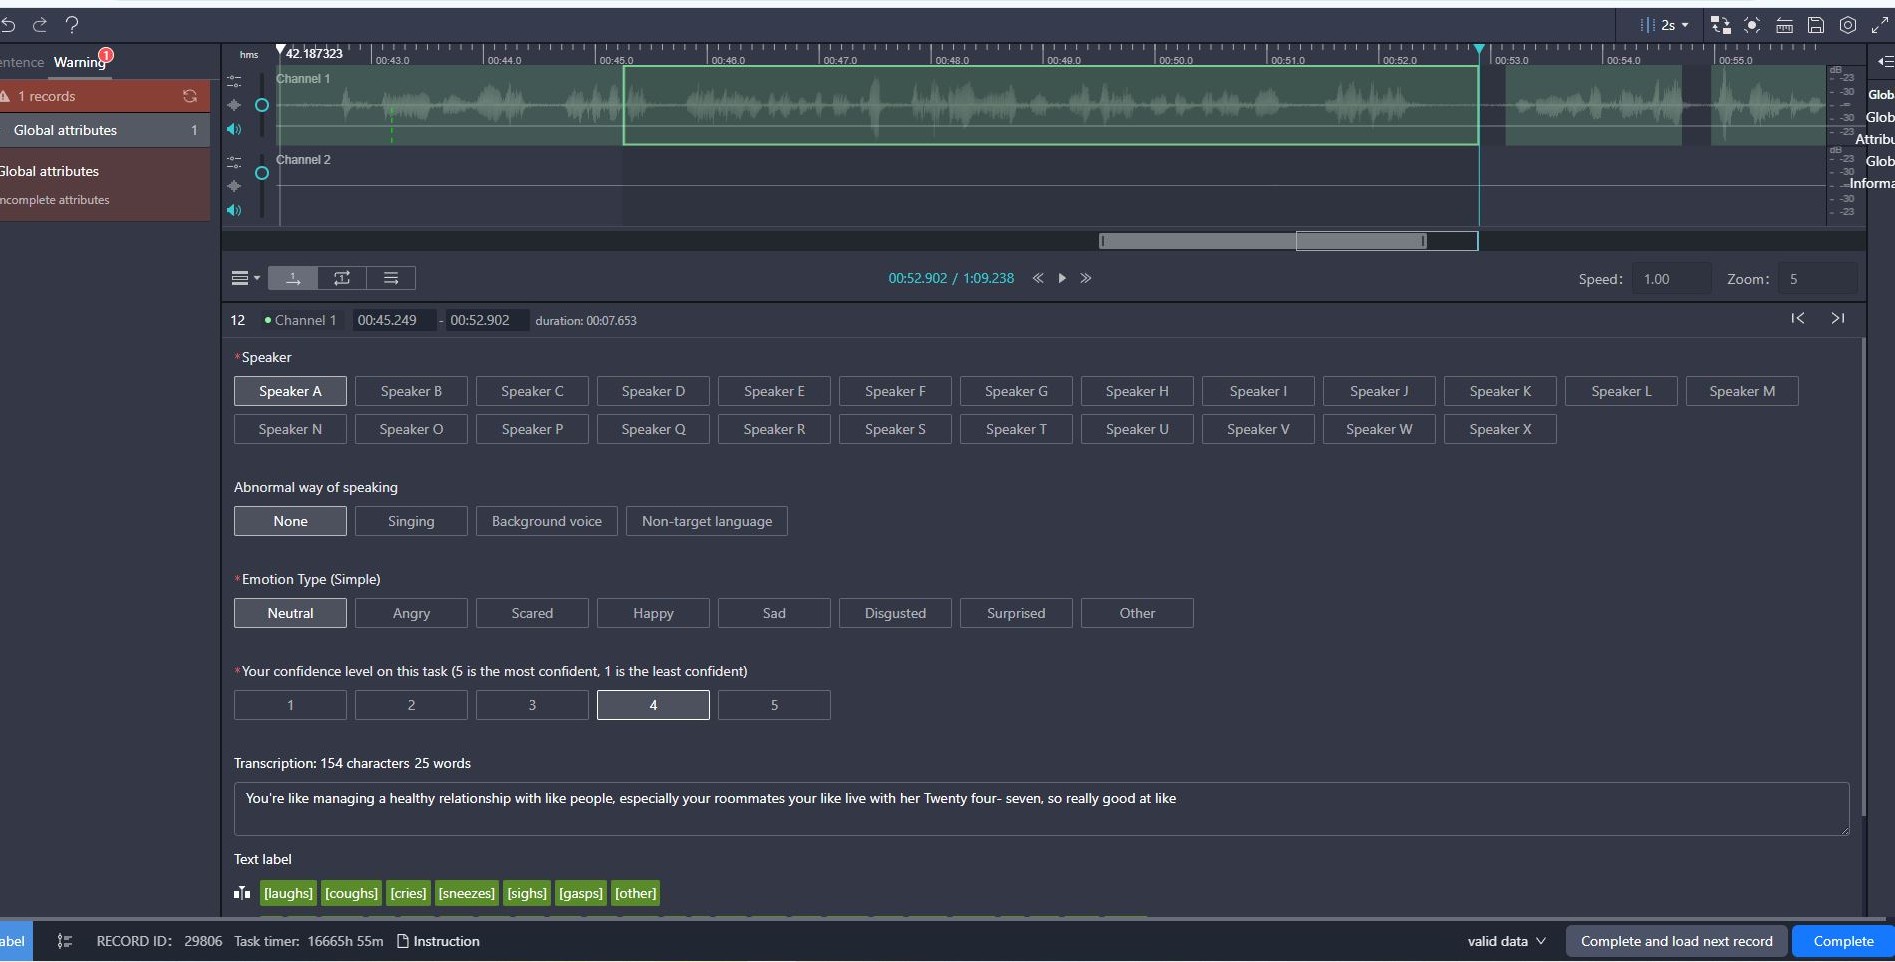
Speaker & audio classification
Word-for-word transcription with speaker turns and timestamps.
Diarization and speaker tagging for multi-party audio.
Sound-event and intent classification for audio pipelines.
Send a short sample, and we'll return transcribed examples and a fixed-scope quote.
Start a pilotVerbatim and normalized transcripts, with timestamps and speaker labels where your guidelines require them.
Yes. Native Spanish and Portuguese contributors and annotators across LATAM deliver authentic, localized speech data.
Speech-to-text and audio labeling with verbatim or normalized transcription, timestamps, and speaker diarization to your guidelines.
Contact us with your data and guidelines. We run a small pilot batch first so you can validate accuracy before committing to full production.
 XYNTRIQ