XYNTRIQ collects and annotates multimodal data: video, text, images, and audio, including egocentric (POV) video, produced in Latin America and India and delivered to enterprise standards.
Send a small sample of your data. We label it against your guidelines so you can measure our quality against your own acceptance criteria.
Fixed scope and a clear cost estimate, typically within 48 hours of the pilot review.
Dedicated domain-matched team with multi-tier QA, batch-level reporting, and a single project owner.
We label and collect training data: image, video, text, audio, and LiDAR, including consented first-person video recorded in Latin America and India.
Image, video, text, audio, LiDAR, point cloud, and multimodal annotation for production-grade models.
Custom image, video, egocentric (POV), audio, speech, and sensor collection across LATAM and India.
Consented egocentric video datasets capturing real-world tasks from a person's own point of view.
Independent validation, auditing, and quality assurance for reliable training data.
Specialist human feedback for model evaluation, prompt assessment, and model training data preparation.
Cleaning, balancing, deduplication, and metadata enrichment of model-ready datasets.
Every dataset starts raw and ends precisely labeled. We're bound by NDA with every client, so we can't show names or logos. Here's the work itself, anonymized for confidentiality.

Crop segmentation & keypoint

Speech-to-text & audio labeling
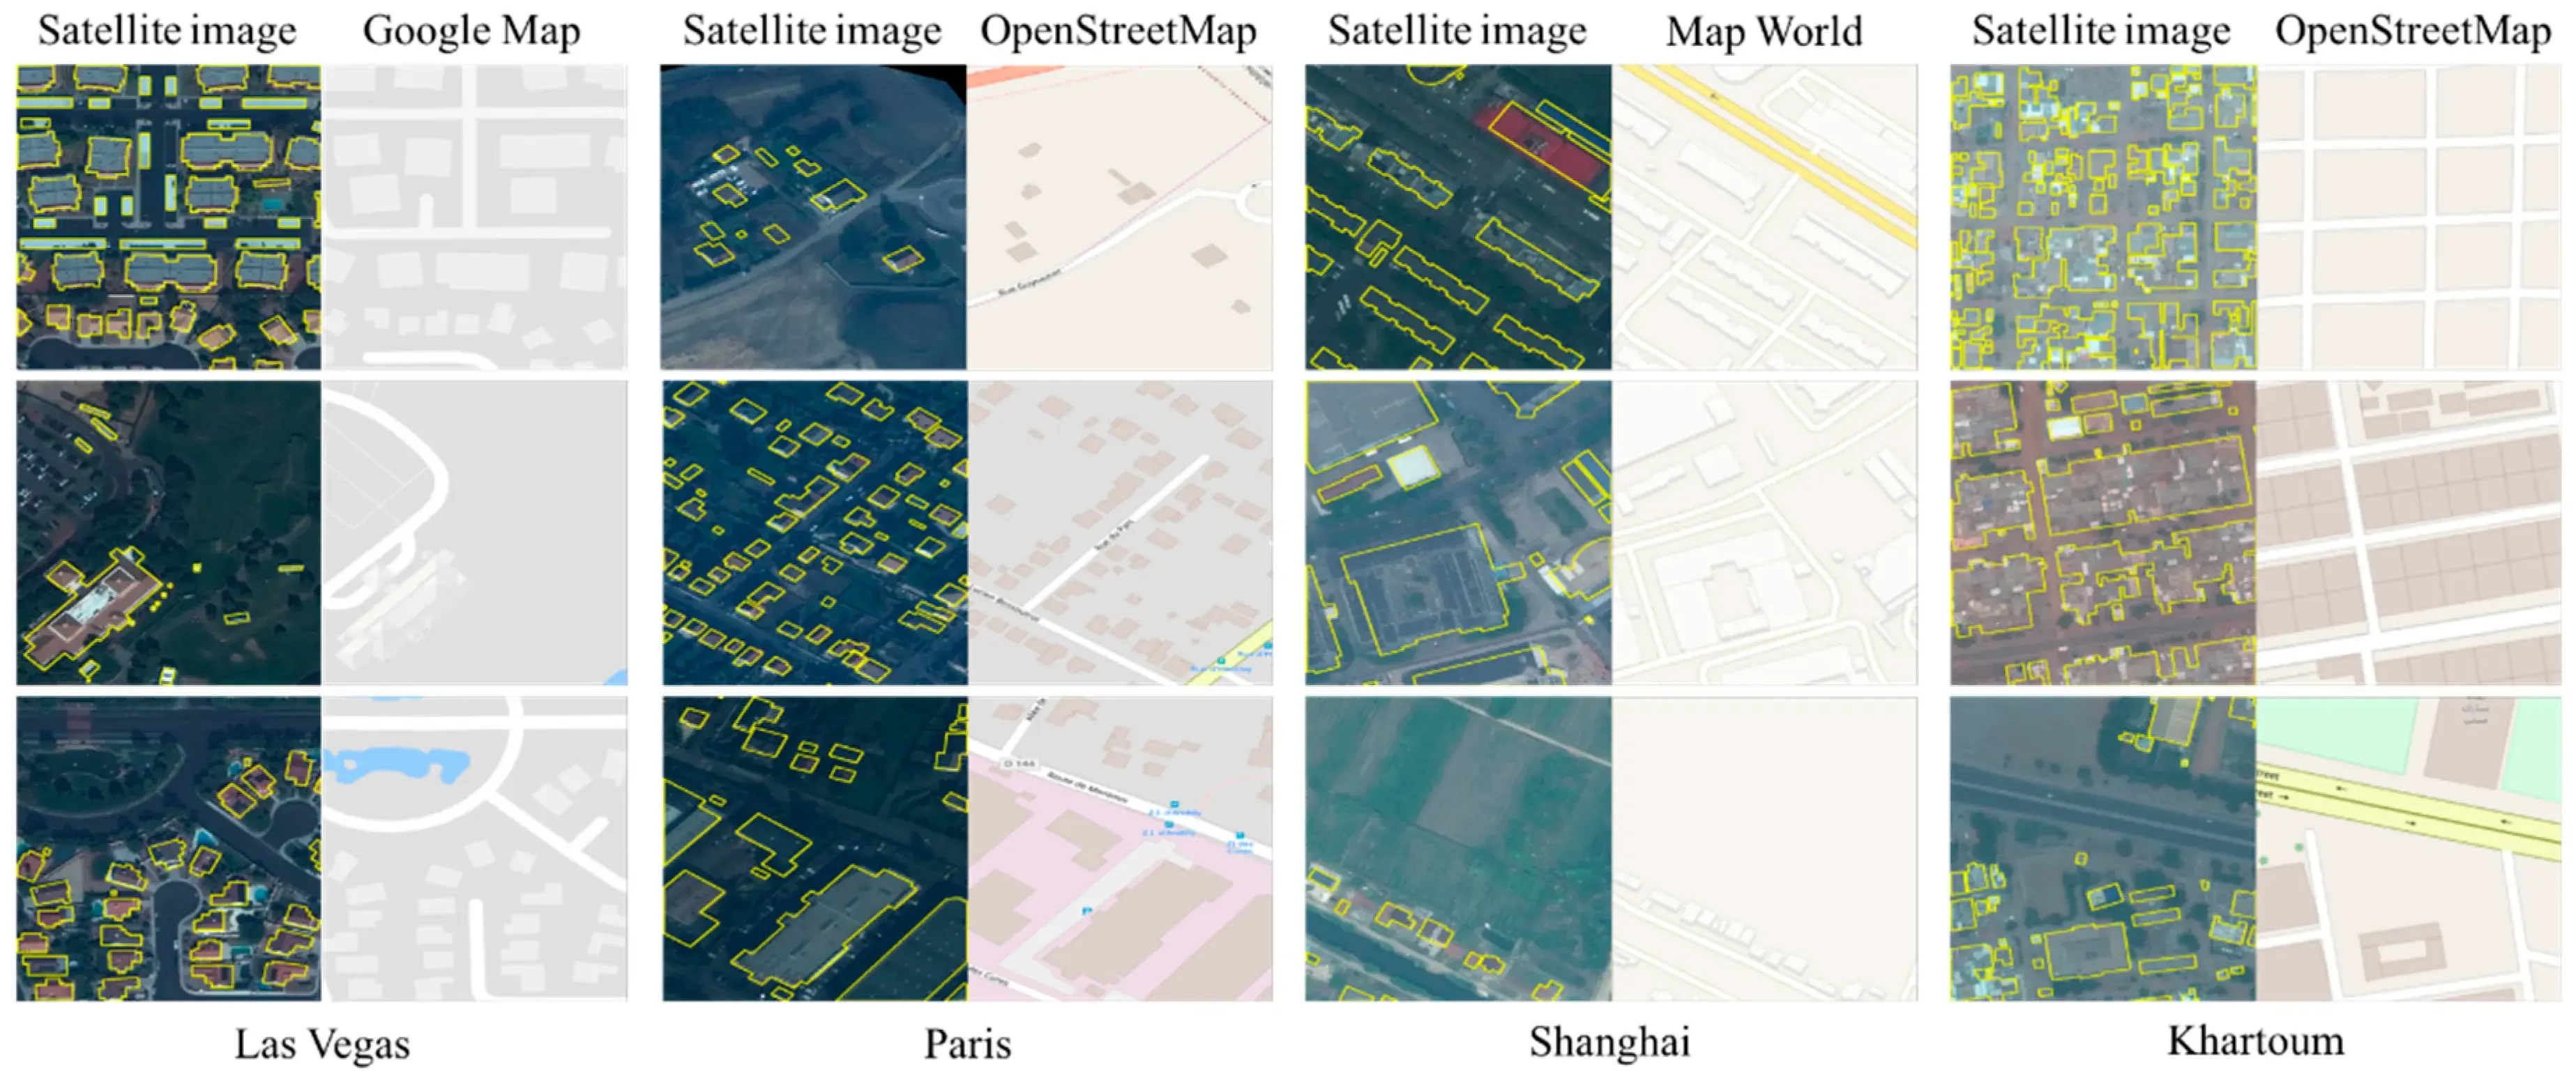
Remote sensing & satellite imagery

3D point cloud labeling

Dense 3D point labelling
Real consented first-person footage from production projects, anonymized under NDA.
First-person video: washing dishes
First-person video: raking leaves
First-person video: washing dishes
Every client engagement is confidential, so names and logos stay private. What we can show is the work itself, and the quality system that backs every batch.
Authentic first-person video for perception models. Our vetted LATAM contributors film real tasks on their own devices, with explicit consent captured per record. Egocentric footage in native Spanish and Portuguese, reviewed in sample batches before we scale.
Organ-level MRI and DICOM segmentation for a healthcare AI pipeline. Domain-matched annotators follow your guidelines with multi-tier QC, and every batch passes internal review before delivery, with a 98%+ accuracy target with auditable labels.
Remote-sensing segmentation and 3D point-cloud labeling for perception teams, with batch-level traceability. Clean, schema-ready outputs arrive with a full quality report, and pilots are quoted within 48 hours.
Rigorous QC and expert teams.
From pilots to enterprise.
Guideline-driven frameworks.
Native Spanish & Portuguese contributors, 24/7.
Healthcare, dental, transportation.
Confidentiality & consent management.
Multi-tier checks + reporting.
Speed without compromise.
Lots of companies sell annotation, and most make the same promise. Here's what usually goes wrong, and how we handle it.
XYNTRIQ runs a vetted contributor network across Latin America, with native Spanish and Portuguese speakers producing consented first-person (POV) video and localized data.
Authentic accents and dialects from local contributors, not synthetic or machine-generated.
Real first-person footage of genuine daily tasks, filmed by vetted contributors.
A growing contributor base that scales from pilot to production without traditional-vendor overhead.
Large enterprises, brands, and government programs need a data partner who is accountable, compliant, and easy to procure from. That's exactly how XYNTRIQ is built.
A Udyam-registered Indian MSME with GST-compliant invoicing, verified identity, and formal procurement readiness.
Datasets processed and stored in India, sovereign-data friendly for government and regulated programs.
NDAs, MSAs, and SOWs handled end-to-end. Your data, guidelines, and models stay confidential.
Multi-tier QC with full traceability. Every label is reviewable, every batch reportable.
Privacy-first data handling with explicit, documented consent for ethical model training.
A dedicated project manager and a scalable workforce, from pilot to production, fast.
Every project follows a transparent, auditable path, built for enterprise and government programs.
Share raw data, guidelines, and quality targets.
Assign a dedicated project lead and confirm the annotation methodology before anything starts.
Review annotated samples and approve scope.
Annotate a small representative batch and deliver a clear cost estimate.
Review and sign. Scope, quality thresholds, and deadlines locked in writing.
Prepare a full confidentiality agreement covering your data, guidelines, and models.
Review sample batches at each milestone and share feedback.
Trained, domain-matched annotators work through your dataset. No batch moves forward without passing internal QC.
Confirm acceptance criteria before final delivery.
Every batch passes automated validation and expert human review; consistency is tracked throughout.
Receive your dataset in the format you need, with a full quality report.
Deliver clean, training-ready data on schedule, with ongoing support and fast iteration.
Join the XYNTRIQ contributor network across India and LATAM. Record everyday tasks first-person (POV) with your smartphone, and help build real-world AI training datasets. A basic head mount is all you need. No professional equipment.
Offer data collection, annotation, and POV video services for XYNTRIQ projects. Registered vendors are contacted for future project availability based on their capability.
Vendor RegistrationData annotation is the process of labeling data such as images, video, text, and audio so AI models can learn from it. XYNTRIQ delivers high-accuracy annotation for production-grade models.
It records real-world tasks from a person's own point of view using a head-mounted smartphone, producing egocentric video used to train computer-vision models.
Data collected from people who have explicitly agreed to its use. This is required for ethical, compliant model training.
Healthcare and medical imaging, dental, autonomous vehicles, agriculture, geospatial, retail, finance, and more, with domain-matched annotators for each.
Multi-tier QC: guideline-driven labeling, automated validation, expert human review, and batch-level traceability with accuracy reporting.
Every engagement is NDA-first, with controlled access, India data residency, and documented consent management for collected data.
Contact us with your data and guidelines. We run a small pilot batch first so you can validate accuracy before committing to full production.
Yes. Every engagement starts with an NDA/MSA covering your data, guidelines, and models, so your information stays confidential from day one.
As soon as we receive your sample data and guidelines. We run the pilot and return a quote typically within 48 hours of reviewing your batch.
 XYNTRIQ
